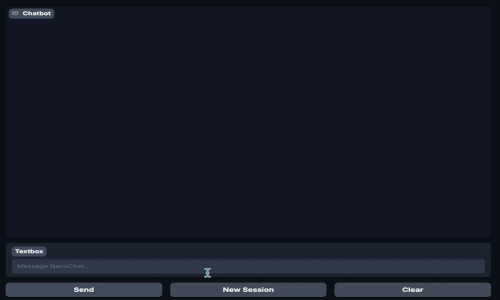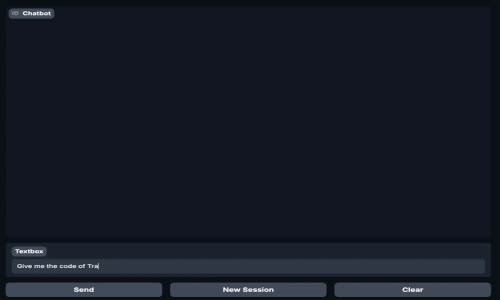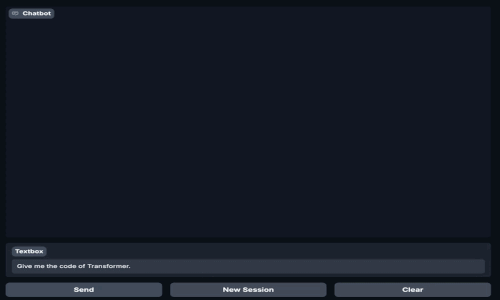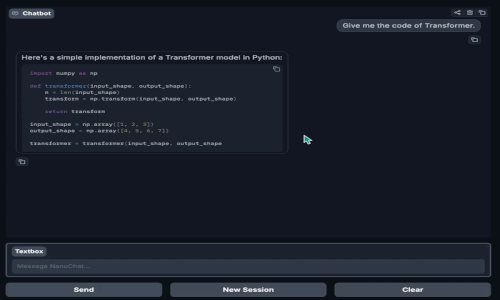
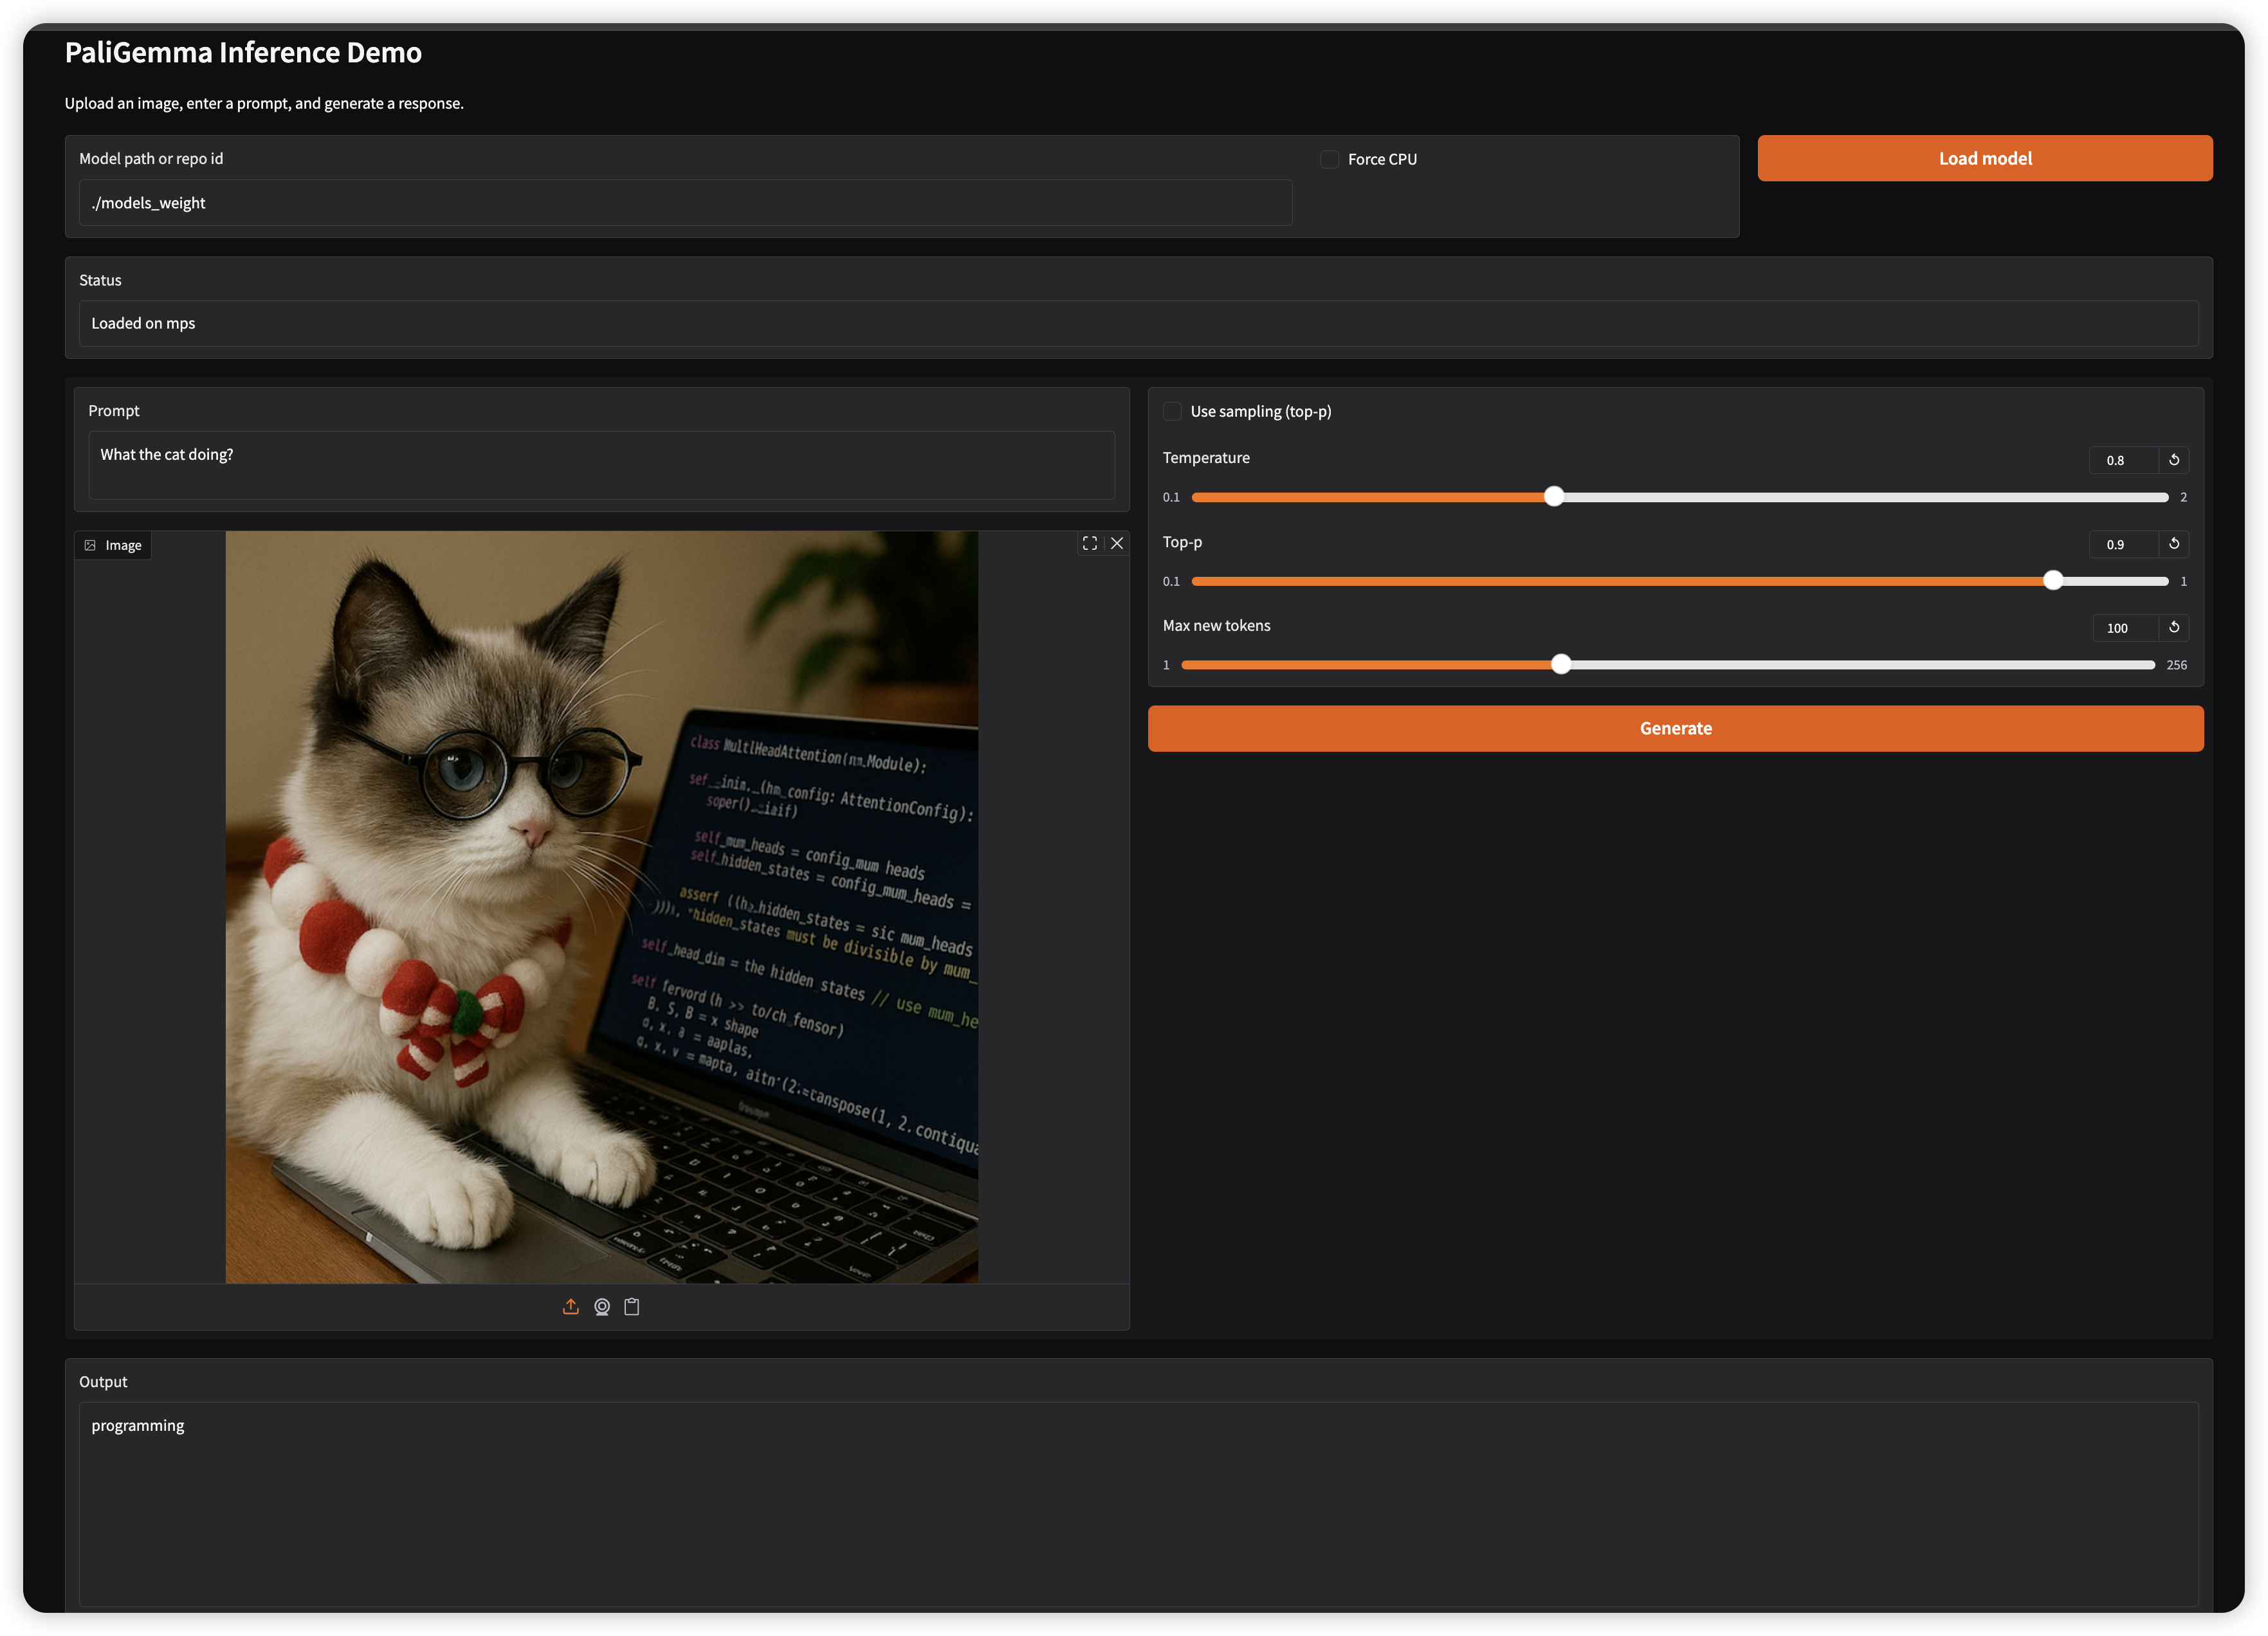
Built an end-to-end LLM stack from scratch, covering scaling law experiments, compute-optimal model sizing, pre-training, supervised fine-tuning, and GRPO-based post-training. Trained a ChatGPT-style conversational model and deployed an interactive demo to showcase instruction following, reasoning, and multi-turn generation.